ICML Oral 2026
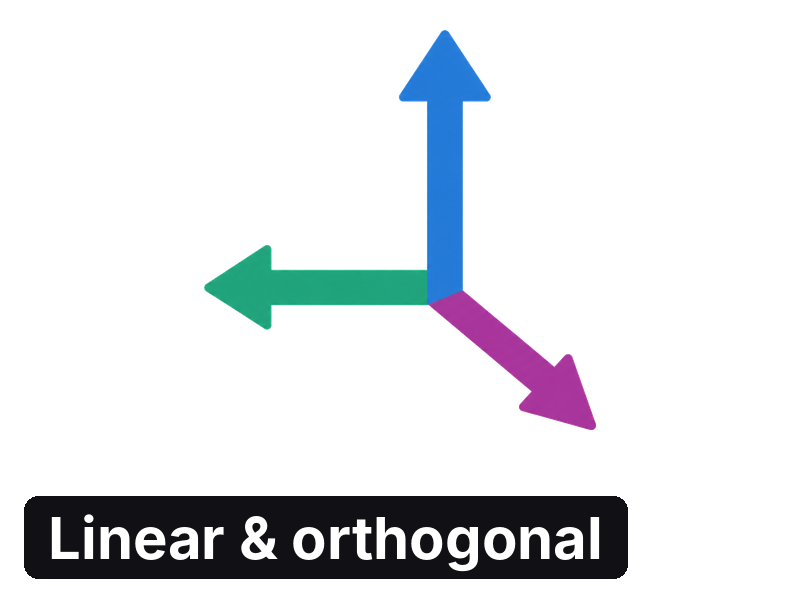
Compositional Generalization Requires Linear, Orthogonal Representations in Vision Embedding Models
Vision models can only recognise familiar parts in new combinations if their representations split into near-orthogonal pieces, one per concept. CLIP, SigLIP and DINO show this structure in part, and the models that show more of it generalise better.